

How Federated AI Could Improve Collaboration Across the GCC
Across the Gulf Cooperation Council, artificial intelligence is creating new opportunities for businesses, hospitals, banks, universities, and government institutions. Organisations increasingly use data to understand customer behaviour, improve services, identify operational risks, and develop more efficient systems.
- 1. Why Federated Learning in the GCC Is Becoming More Relevant
- 2. How Federated Learning Works Without Centralising Raw Data
- 3. How Gulf Banks Could Use Federated Learning to Improve Fraud Detection
- 4. Could Healthcare, Energy and Universities Benefit From Collaborative AI?
- 5. What GCC Data Protection Laws Mean for Federated Learning
- 6. The Privacy and Cybersecurity Risks of Federated Learning
- 7. The Future of Federated Learning and Secure AI Collaboration in the GCC
- Conclusion
However, valuable information is often distributed across different organisations.
A hospital may hold medical records that could support research into disease detection. A bank may possess transaction information relevant to identifying financial fraud, while an industrial company may collect equipment data that could help predict machinery failures.
Combining insights from these sources could improve certain AI applications, but transferring sensitive datasets into one central database can introduce legal, commercial, and cybersecurity concerns.
This is why federated learning in the GCC could become an important part of the region’s digital transformation.
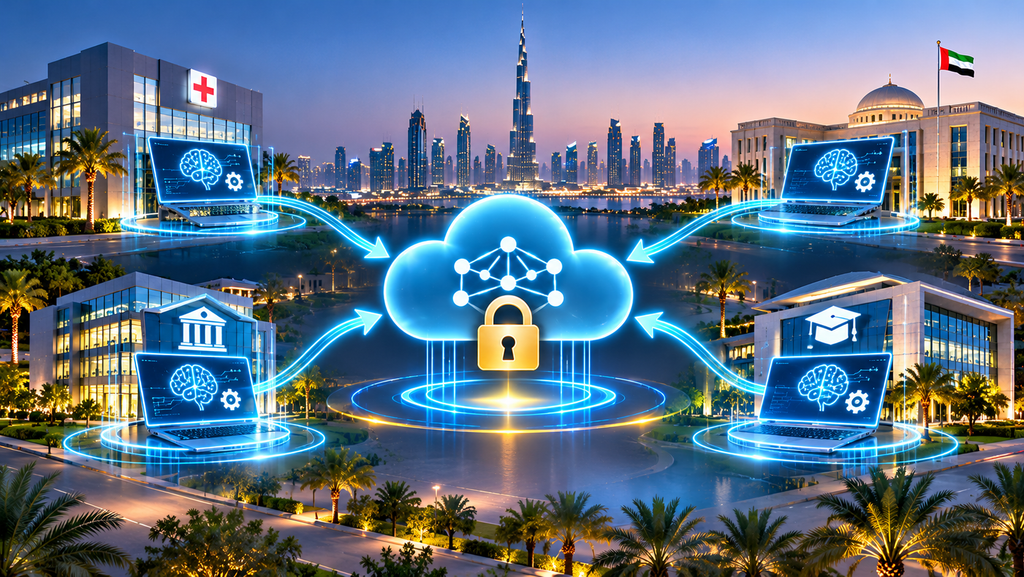
Federated learning is a machine learning approach that allows multiple organisations or devices to participate in training a shared model while generally keeping their underlying training datasets within their respective systems.
Instead of requiring every participating organisation to send its original records to one central location, the approach exchanges selected model updates or related computational information.
This can reduce the need to transfer raw datasets, potentially making collaboration more practical in environments where information must be carefully controlled.
Across the UAE, Saudi Arabia, Qatar, Bahrain, Oman, and Kuwait, digital transformation strategies are creating increasing demand for responsible AI development.
Research institutions in Saudi Arabia and the UAE have already published studies exploring federated learning for financial fraud detection. International organisations, including NIST and European data protection authorities, are also examining how federated methods can be combined with stronger privacy technologies.
However, federated learning does not guarantee complete confidentiality.
Model updates may reveal information about their training data, while poorly secured systems can remain vulnerable to malicious participants, inaccurate information, and cyberattacks.
Understanding these opportunities and limitations explains how federated learning could help Gulf organisations collaborate more effectively while maintaining appropriate safeguards for sensitive information.
1. Why Federated Learning in the GCC Is Becoming More Relevant
Modern artificial intelligence systems often depend on access to large amounts of relevant information.
The quality, diversity, and consistency of training data can influence how well an AI model performs.
However, organisations may be unable or unwilling to combine their information because of privacy requirements, contractual obligations, competitive concerns, or technical restrictions.
The Challenge of Fragmented Data
A financial institution may have useful transaction information but limited visibility into fraud patterns experienced by other banks.
A healthcare provider may treat patients with particular conditions but lack sufficient examples to develop a reliable research model independently.
Similarly, industrial companies may operate comparable equipment while maintaining separate maintenance databases.
These situations create potential opportunities for collaboration.
However, combining the underlying records may not be necessary for every analytical objective.
Understanding Federated Learning
Federated learning enables participating systems to train models using locally stored information.
A coordinating system may distribute an initial model to participating organisations.
Each organisation trains the model using its own dataset and produces an update.
Selected updates are combined to improve the shared model.
The process may then be repeated across several training rounds.
How It Differs From Centralised AI
Traditional centralised machine learning commonly requires information to be collected within a shared environment.
Federated learning distributes some of the training work across separate environments.
However, the coordinating system may still process information derived from local data.
That information can remain sensitive and must be protected appropriately.
AI Collaboration Models Compared
| Model | How Data Is Handled | Main Consideration |
|---|---|---|
| Centralised Learning | Training data collected centrally | Data transfer and concentration risks |
| Federated Learning | Training occurs in participating environments | Model update leakage |
| Split Learning | Different portions of model computation are distributed | Intermediate information exposure |
| Secure Data Enclave | Approved analysis within a controlled environment | Access governance |
| Aggregated Statistical Sharing | Institutions exchange selected summary results | Limited analytical detail |
| Synthetic Data | Artificial records generated for selected uses | Fidelity and residual privacy risks |
Why Local Control Matters
Federated learning may allow organisations to retain greater operational control over their original data.
However, retaining records locally does not necessarily mean retaining exclusive control over every inference made from them.
Effective collaboration requires clear agreements governing the shared model and its outputs.
2. How Federated Learning Works Without Centralising Raw Data
Federated learning is often described as training an AI model without sharing data.
That description captures its basic purpose but can be misleading if interpreted as meaning that no information leaves an organisation.
The distinction between raw data and model-derived information is essential.
The Local Training Process
Consider a hypothetical collaboration between three financial institutions.
Each institution stores its transaction records on its own systems.
A coordinating service distributes a machine learning model to the participants.
Each institution trains the model using approved local data and prepares an update describing the changes learned during training.
These updates are then processed to create an improved shared model.
The participating institutions may repeat the process.
Horizontal Federated Learning
Horizontal federated learning is useful when organisations hold similar types of information about different individuals or records.
For example, several hospitals might collect comparable medical imaging data from different patients.
They may collaborate on training a model using a common set of features.
However, differences in imaging equipment and clinical practices can affect the quality of the training process.
Vertical Federated Learning
Vertical federated learning involves organisations holding different information about overlapping entities.
For example, two businesses might each hold different categories of information concerning some of the same customers.
This arrangement requires particular care when matching records and protecting intermediate computations.
Entity matching itself can create privacy risks.
Federated Analytics
Not every collaboration requires training a complex predictive model.
Federated analytics can support selected statistical calculations across distributed datasets.
An authorised group of organisations might seek an aggregated result without transferring all underlying records.
However, the sensitivity of outputs depends on the query, dataset size, and safeguards.
A Simplified Federated Learning Workflow
| Stage | Main Activity |
|---|---|
| 1. Define Objective | Agree on a legitimate research or business purpose |
| 2. Approve Participation | Establish legal, technical and governance conditions |
| 3. Prepare Local Data | Standardise information within each organisation |
| 4. Distribute Model | Provide the initial model to approved participants |
| 5. Train Locally | Update the model using local datasets |
| 6. Protect Updates | Apply suitable security and privacy controls |
| 7. Aggregate | Combine approved model updates |
| 8. Validate | Assess performance, privacy and possible bias |
| 9. Deploy if Appropriate | Introduce the model with necessary safeguards |
Why Security Must Be Built Into the Process
A system that keeps raw records local can still be insecure.
NIST has explained that model updates can reveal sensitive information through particular attack techniques.
Federated learning should therefore be treated as an architectural approach that can support privacy, not as a complete privacy guarantee.
3. How Gulf Banks Could Use Federated Learning to Improve Fraud Detection
Financial institutions are a particularly relevant potential application because they hold sensitive transaction information and face overlapping types of financial crime.
A fraud pattern detected by one bank might also be relevant to another.
However, banks cannot simply combine customer records without considering confidentiality, regulation, and security.
Collaborative Fraud Detection
A federated approach could allow participating institutions to train a shared model using approved transaction information kept within their respective systems.
The model might learn patterns associated with potentially fraudulent activity across a wider range of training examples.
However, learning from more institutions does not automatically improve accuracy.
Data quality, class imbalance, changing fraud behaviour, and differences between financial institutions can influence performance.
Research From Saudi Arabia
A study published in September 2025, titled A Federated Approach to Scalable and Trustworthy Financial Fraud Detection, introduced a federated fraud-detection framework.
The research received support from King Abdulaziz University in Saudi Arabia and the University of Plymouth.
It explored how financial institutions could collaborate on fraud detection without sharing raw transaction records.
However, the publication describes a research framework rather than confirming a production network connecting Saudi banks.
Research From the UAE
A March 2025 study involving researchers from Skyline University College in Sharjah examined explainable AI and federated learning for financial fraud detection.
The research explored methods for improving collaborative fraud analysis while making model decisions more interpretable.
Explainability is important because financial institutions may need to understand why a model identifies a transaction as suspicious.
However, explaining a model’s decision does not necessarily establish that the decision is correct.
Potential Banking Applications
| Application | Possible Benefit | Main Limitation |
|---|---|---|
| Fraud Detection | Broader model training | False alarms and privacy risks |
| Financial Distress Analysis | Shared analytical learning | Data comparability |
| Cybersecurity Monitoring | Recognition of selected attack patterns | Sensitive security data |
| Risk Modelling | Collaborative statistical analysis | Bias and institutional differences |
| Anti-Money Laundering Research | Investigation of detection techniques | Strict legal and operational controls |
Why Financial Institutions Need Governance
Fraud-detection models can affect customers.
Incorrect alerts may lead to transaction delays or additional scrutiny.
Consequently, any collaborative model requires appropriate human oversight, testing, and procedures for reviewing decisions.
Federated learning does not remove these responsibilities.
4. Could Healthcare, Energy and Universities Benefit From Collaborative AI?
The potential value of federated learning extends beyond banking.
Healthcare institutions, industrial businesses, universities, and technology companies may benefit from training models using information distributed across several organisations.
However, different sectors present different levels of sensitivity and technical complexity.
Healthcare Research
Hospitals may hold separate records relevant to medical research.
A federated model could potentially help researchers study selected conditions without routinely copying all patient records into one research database.
Possible applications include medical image analysis and certain predictive research tasks.
However, these projects still require clinical validation, appropriate permissions, and strict protection of health information.
An AI system suitable for academic research is not automatically authorised for clinical use.
Saudi Research Into Multi-Hospital Systems
A study first published online in April 2026 examined an energy-aware federated learning framework for multi-hospital environments.
Researchers affiliated with Jazan University contributed to the work.
The study explored the technical challenges of communication efficiency and model training across distributed healthcare systems.
It should be understood as research rather than evidence of nationwide hospital deployment.
Energy and Industrial Maintenance
Industrial companies collect equipment information from sensors, production systems, and maintenance records.
Organisations operating similar assets may be interested in learning from one another’s historical equipment behaviour.
A federated model could potentially identify patterns associated with equipment failures without requiring companies to transfer complete operational datasets.
However, differences in equipment types, maintenance standards, and operating conditions can reduce model reliability.
Commercial confidentiality must also be protected.
University Collaboration
Universities may collaborate on research involving distributed datasets.
Federated learning could support projects where institutions are unable to centralise sensitive source information.
This may be relevant to selected studies in healthcare, cybersecurity, engineering, and public services.
However, institutional research approval and data rights remain necessary.
Potential Sector Applications
| Sector | Possible Application | Important Requirement |
|---|---|---|
| Healthcare | Medical research and selected AI models | Patient protection and clinical validation |
| Banking | Fraud and risk research | Financial confidentiality |
| Energy | Predictive equipment maintenance | Industrial data security |
| Universities | Joint research | Ethical approval and data governance |
| Telecommunications | Network anomaly detection | Network security |
| Public Services | Selected cross-agency analytics | Lawful processing and accountability |
Why Practical Value Should Come First
Federated learning should not be adopted simply because an organisation has sensitive data.
If a problem can be solved effectively using local analysis or appropriately aggregated statistics, a complex federated system may not be justified.
The chosen approach should reflect the actual objective and risk.
5. What GCC Data Protection Laws Mean for Federated Learning
Data protection regulation is an important consideration for organisations exploring collaborative AI.
Although federated learning can reduce some data-transfer requirements, it does not automatically eliminate obligations under privacy and sector-specific laws.
The UAE’s Personal Data Protection Framework
The UAE’s Federal Decree-Law No. 45 of 2021 establishes a federal framework for personal data protection.
It addresses personal data processing and cross-border transfers, subject to the law’s scope and exclusions.
Certain categories, including health data, banking data, and activities governed by particular free-zone frameworks, may be subject to separate legal arrangements.
Consequently, a financial institution or hospital cannot assume that the general federal law is the only applicable source of obligations.
Saudi Arabia’s Personal Data Protection Law
Saudi Arabia’s Personal Data Protection Law establishes requirements for processing personal information.
The Saudi Data and Artificial Intelligence Authority provides guidance on the responsibilities of data controllers and processors.
Saudi Arabia also has regulations governing transfers of personal data outside the Kingdom.
These rules are relevant when considering whether model updates or other information exchanged during federated training constitute regulated personal data.
Qatar’s Privacy Protection Law
Qatar’s Law No. 13 of 2016 provides a framework for protecting personal data.
The government has issued guidance to help organisations understand their responsibilities.
Institutions considering collaborative AI should assess processing purposes, lawful grounds, confidentiality, and other applicable requirements.
Bahrain’s Data Protection Requirements
Bahrain’s Personal Data Protection Law No. 30 of 2018 governs the processing of personal information.
Collaborative AI projects involving Bahraini data should evaluate relevant legal requirements, particularly when information is sensitive or transferred between entities.
Oman’s Data Protection Framework
Oman’s Personal Data Protection Law was issued through Royal Decree No. 6 of 2022.
Its executive regulations were issued in 2024.
The law was subsequently amended by Royal Decree No. 68 of 2026.
Organisations must review the applicable consolidated requirements, including those concerning sensitive data and international processing.
Selected GCC Legal Frameworks
| Country | Relevant Framework | Federated Learning Consideration |
|---|---|---|
| UAE | Federal Personal Data Protection Law and applicable sector-specific laws | Scope and cross-border processing |
| Saudi Arabia | Personal Data Protection Law and transfer regulations | Lawful processing and international transfers |
| Qatar | Personal Data Privacy Protection Law | Processing and confidentiality |
| Bahrain | Personal Data Protection Law | Sensitive data and sharing obligations |
| Oman | Personal Data Protection Law, as amended | Permissions and processing controls |
| Kuwait | Applicable sectoral and electronic data rules | Project-specific legal review |
Why Local Data Storage Is Not Automatic Compliance
A federated system may keep original datasets within each participating institution.
However, model updates, identifiers, metadata, and output information can still create privacy risks.
Data protection obligations depend on the actual information being processed and the relevant legal framework.
6. The Privacy and Cybersecurity Risks of Federated Learning
Federated learning offers opportunities to reduce unnecessary data movement, but it also introduces vulnerabilities.
Privacy risks can arise during model training, aggregation, and deployment.
A secure architecture must address these different stages.
Model Inversion and Gradient Leakage
Some attacks attempt to infer information about training records from model parameters or gradients.
NIST has documented how information can sometimes be reconstructed or inferred from model updates.
Consequently, institutions should not assume that exchanging model parameters is always harmless.
The exact risk depends on the model, dataset, training procedure, and attacker capabilities.
Membership Inference
Membership inference attempts to determine whether a particular individual’s record was used to train a model.
This can be sensitive in healthcare, finance, or other confidential applications.
Protecting raw data during training does not automatically eliminate this risk.
Model Poisoning
A malicious or compromised participant could submit misleading updates.
These updates might reduce model accuracy or influence predictions in undesirable ways.
Collaborative systems therefore require participant authentication, monitoring, and appropriate defensive controls.
Differential Privacy
Differential privacy is a mathematical framework that limits the extent to which an individual’s information influences a released result.
It can be incorporated into some federated learning processes.
However, stronger privacy protection can affect model accuracy.
The trade-off must be evaluated for the intended application.
Secure Aggregation
Secure aggregation can allow a coordinating server to combine selected model updates without directly viewing every participant’s individual update.
This reduces certain information exposure risks.
However, the design must account for failures, malicious participants, and other operational conditions.
Privacy Technologies Compared
| Protection | Main Purpose | Important Limitation |
|---|---|---|
| Secure Aggregation | Protect individual updates during combination | Protocol complexity |
| Differential Privacy | Reduce information leakage | Utility and accuracy trade-offs |
| Homomorphic Encryption | Enable calculations on encrypted information | Computational overhead |
| Secure Multiparty Computation | Protect collaborative calculations | Communication and operational costs |
| Access Controls | Restrict system use | Credential management |
| Auditing | Record relevant activity | Requires review and enforcement |
Why Defence in Depth Matters
No individual privacy technology addresses every possible threat.
A secure federated learning system may combine multiple safeguards with conventional cybersecurity practices.
These include secure software development, access management, network protection, incident response, and ongoing assessment.
7. The Future of Federated Learning and Secure AI Collaboration in the GCC
Federated learning could become increasingly relevant as Gulf organisations develop AI applications while facing growing expectations around data protection and cybersecurity.
However, its adoption should be driven by demonstrable benefits, not assumptions that decentralisation automatically improves privacy.
Building Collaborative AI Partnerships
Organisations considering federated learning should begin by identifying a shared problem that participants cannot address equally well on their own.
For example, several institutions may wish to develop a model using information from different environments.
They should agree on objectives, responsibilities, and measurable outcomes before beginning technical development.
The Importance of Data Standardisation
Federated learning is difficult when participating organisations use incompatible data definitions.
A bank may classify transaction events differently from another institution.
Hospitals may use different clinical coding systems.
Common data standards and documented processing procedures can help improve the reliability of collaborative training.
However, standardisation should not require unnecessary disclosure of sensitive records.
Starting With Controlled Pilot Projects
Organisations may begin with synthetic, public, or suitably authorised datasets to evaluate technical feasibility.
A limited pilot can help identify issues involving communication performance, model accuracy, privacy, and operating costs.
However, successful testing with synthetic data does not prove that the system will perform equally well with real-world records.
A Practical Federated Learning Implementation Checklist
- Identify a clear business or research purpose.
- Confirm that federated learning is appropriate for the problem.
- Identify participating organisations and responsibilities.
- Review applicable privacy and sector-specific laws.
- Obtain necessary approvals and establish lawful processing arrangements.
- Assess risks from model updates and final outputs.
- Establish secure participant authentication.
- Standardise data definitions and training procedures.
- Consider secure aggregation and differential privacy.
- Develop controls against malicious or unreliable updates.
- Test model performance across participating institutions.
- Establish ownership and use rights for the trained model.
- Document security incidents and responsibilities.
- Evaluate operational costs and benefits.
- Monitor models after deployment.
How Should Organisations Measure Success?
The number of participants in a federated network does not prove that collaboration is effective.
Performance must be assessed against a meaningful baseline.
Suggested Performance Indicators
| Indicator | What It Measures |
|---|---|
| Model Performance | Accuracy and reliability |
| Privacy Risk | Exposure through updates and outputs |
| Regulatory Compliance | Adherence to applicable requirements |
| Participant Coverage | Representation of relevant datasets |
| Training Efficiency | Computing and communication resources |
| Security Incidents | System resilience |
| Model Fairness | Performance across relevant groups |
| Collaboration Value | Improvement over local-only approaches |
| Operational Cost | Financial sustainability |
| Governance Quality | Accountability and oversight |
Opportunities for Gulf Technology Businesses
Demand for privacy-preserving AI could create opportunities for cybersecurity specialists, cloud technology providers, machine learning companies, and data governance consultants.
Universities may also contribute research expertise involving privacy engineering, encrypted computation, and distributed machine learning.
However, technology providers should avoid claiming that federated learning guarantees anonymity or eliminates legal responsibility.
Why Trust Will Remain Central
Organisations are more likely to collaborate when they understand how information will be handled and who will be accountable for its use.
Federated learning may provide a technical foundation for selected partnerships.
However, lasting cooperation also depends on transparent agreements, independent security assessment, and trustworthy institutional governance.
Conclusion
Federated learning could help Gulf organisations collaborate on artificial intelligence without routinely transferring their underlying sensitive datasets into a shared central repository.
This approach may be useful for selected applications in healthcare, banking, industrial maintenance, cybersecurity, and academic research.
Research involving institutions in Saudi Arabia and the UAE demonstrates increasing regional interest in collaborative machine learning, particularly for financial fraud detection.
Meanwhile, guidance from NIST and European data protection authorities highlights both the potential advantages and important limitations of federated systems.
However, keeping raw data within an organisation does not guarantee that the information remains private.
Model updates can reveal sensitive details, while malicious participants and poorly designed systems can create additional risks.
For Gulf organisations, successful adoption will depend on combining technical safeguards with appropriate legal compliance, cybersecurity, data governance, and operational accountability.
For policymakers and regulators, the challenge is to support responsible innovation while maintaining effective data protection.
For technology developers, the opportunity lies in building systems that improve collaboration without relying on unsupported claims of complete security.
Ultimately, federated learning should be understood as one possible tool for responsible AI development rather than a universal replacement for secure data-sharing systems.
When used appropriately, it could help GCC institutions learn from broader information while retaining stronger control over the sensitive records entrusted to them.
Do follow us on Instagram
Read More – Can Autonomous Inspection Drones Improve the Maintenance of Gulf Infrastructure?